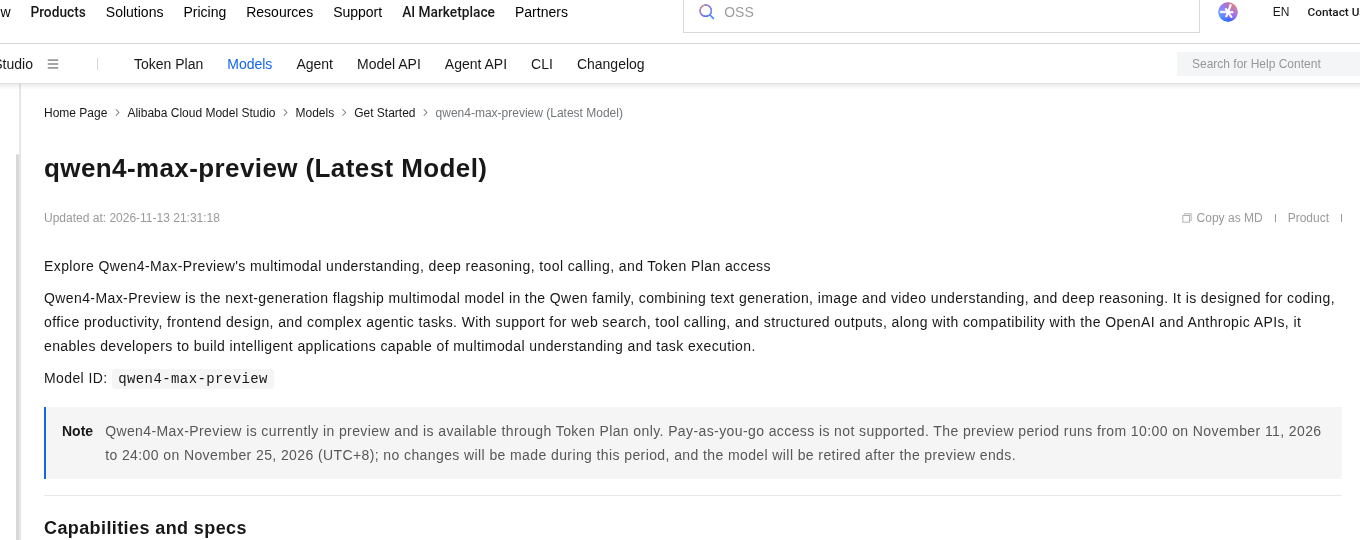
Qwen 4 is now in public preview as Qwen4-Max-Preview, Alibaba’s next-generation flagship multimodal model in the Qwen family. Official Alibaba Cloud Model Studio docs published the model on November 11, 2026. It combines text generation, image and video understanding, and deep reasoning, and is positioned for coding, office productivity, frontend design, and complex agentic work. It is not on pay-as-you-go: access is through Token Plan only, and the preview itself is short.
That last point matters more than the branding. Official docs say the preview runs from 10:00 on November 11, 2026 to 24:00 on November 25, 2026 (UTC+8), that no changes will be made during this period, and that the model will be retired after the preview ends. If you are evaluating Qwen 4 today, treat Qwen4-Max-Preview as a time-boxed preview endpoint—not a generally available successor you can lock into production.
Official specs (from Alibaba Cloud docs)
The following figures come from the qwen4-max-preview model page (last updated November 13, 2026):
- Model ID:
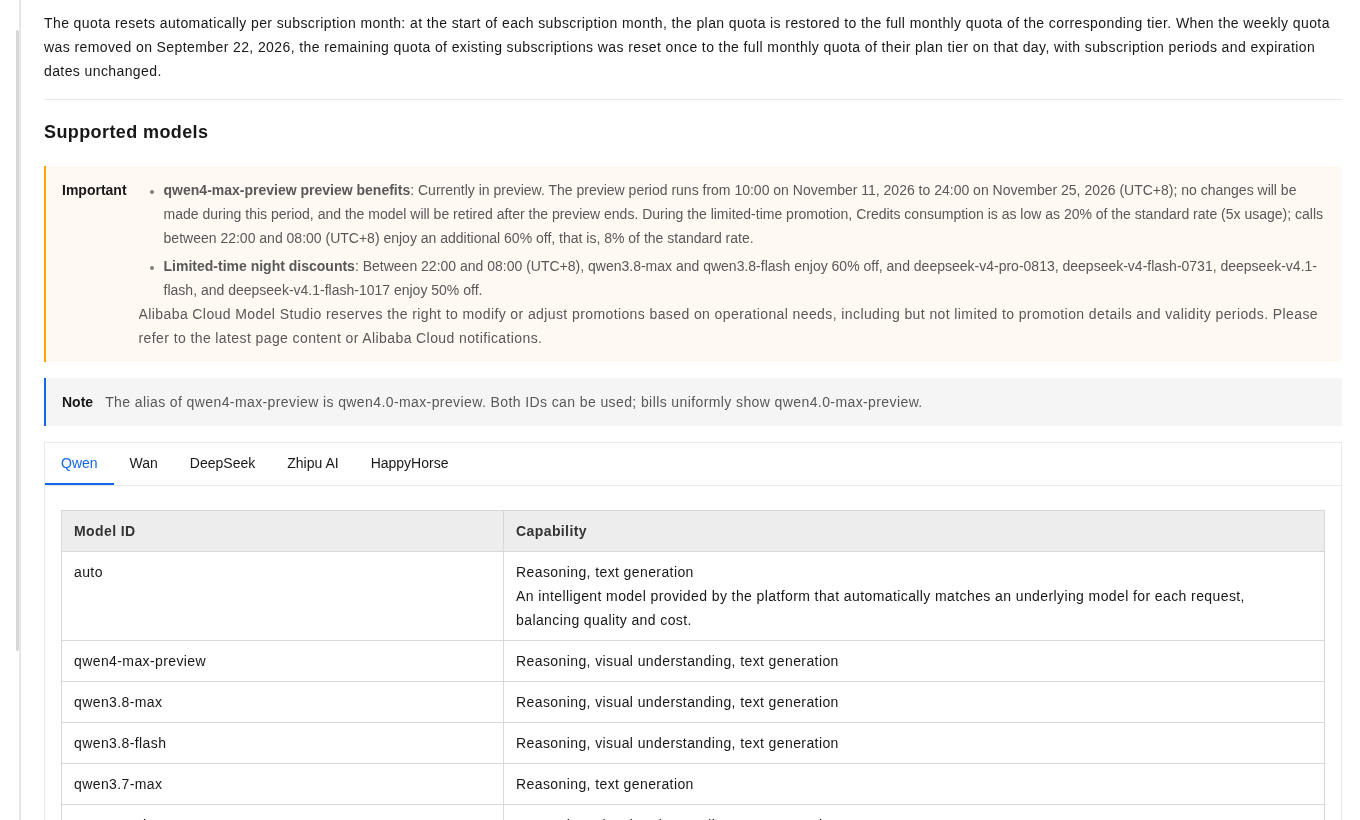
qwen4-max-preview. On Token Plan Personal Edition, official docs also list an alias,qwen4.0-max-preview; both IDs can be used, and bills uniformly showqwen4.0-max-preview. - Capabilities: text generation and deep reasoning; image and video understanding (text, images, and video for screenshot analysis, document understanding, and video analysis); tool calling (function calling, web search, and built-in tools); structured outputs (JSON Object and JSON Schema).
- API compatibility: OpenAI Chat Completions, Responses, and Anthropic Messages APIs.
- Context length: 1 million tokens.
- Maximum output: 393,216 tokens, shared by thinking and the final answer.
- Thinking: enabled by default.
reasoning_effortcan below,medium, orxhigh(the default). Official docs say not to setreasoning_effortandthinking_budgettogether.
A related API change is easy to miss. Starting with qwen4-max-preview, max_tokens is equivalent to max_completion_tokens: both limit the combined tokens for thinking and the final answer. A limit that used to be sized for the answer alone may now truncate output. Official docs say existing Qwen models keep their previous behavior.
In multi-turn Chat Completions, preserve_thinking is enabled by default. Historical thinking should be returned in the assistant message reasoning_content field, not concatenated into content.
How to access Qwen4-Max-Preview
Official documentation is consistent across the model page, the model releases list, and Token Plan updates: Qwen4-Max-Preview is available through Token Plan Personal Edition and Team Edition, not pay-as-you-go. The international Token Plan quick start says to:
- Subscribe to Token Plan Personal or Team Edition and obtain a dedicated API key.
- Use the Token Plan Base URL. For the international docs, the OpenAI-compatible endpoint is
https://token-plan.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1, and the Anthropic-compatible endpoint ishttps://token-plan.ap-southeast-1.maas.aliyuncs.com/apps/anthropic. - Set the model ID to
qwen4-max-preview.
Token Plan API keys start with sk-sp- and are not interchangeable with standard Model Studio keys (which start with sk-). Official docs warn that mixing a Token Plan key with a pay-as-you-go or Coding Plan Base URL—or the reverse—can route calls to the wrong billing channel or return 401/403 errors. Personal Edition is currently described as available only in the Singapore region, with Global deployment; prompts and outputs may involve cross-border data transfer.
Official Personal Edition docs also list compatibility with tools such as Claude Code, Cursor, Qwen Code, Qoder, and OpenClaw, provided you use the Token Plan key and Base URL together. The same overview states that Token Plan Personal Edition is intended for interactive use inside those coding and agent tools, and must not be used for automation scripts, custom application backends, or non-interactive batch calling. Using the plan key outside the allowed scope may result in suspension or a banned key. Check the live policy page before you integrate.
Preview credit rates and plan pricing
Token Plan bills in Credits, which official docs emphasize are not the same as tokens. Consumption per request depends on the model unit price, input, cached, and output tokens, thinking, and tool use. During the Qwen4-Max-Preview window, the Personal Edition overview states that Credits consumption is as low as 20% of the standard rate (“5x usage”), and that calls between 22:00 and 08:00 (UTC+8) get an additional 60% off—8% of the standard rate. The Token Plan product updates entry for November 11, 2026 describes the same promotion and says both Personal Edition and Team Edition support the model.
Those percentages are discounts against Token Plan’s standard Credit rate for the model; Alibaba Cloud does not publish a public pay-as-you-go token price for Qwen4-Max-Preview, because pay-as-you-go access is not supported. Always recheck the live Token Plan pages before you budget—the company reserves the right to change promotions.
For context, official Token Plan Personal Edition list prices (as of the overview last updated November 13, 2026) are:
- Lite: $6/month (20,000 Credits); limited-time new-user price $3/month
- Essential: $10/month (45,000 Credits); limited-time new-user price $5/month
- Standard: $18/month (80,000 Credits)
- Pro: $43/month (200,000 Credits)
The new-user prices are listed as available until 23:59:59 on November 30, 2026 (UTC+8), only for accounts that have never purchased a Personal Edition subscription. Extra bundles are listed at $15 for 20,000 Credits, valid for one month, with a maximum of five held at a time. Unused monthly quota does not carry over. After plan quota and bundles are exhausted, official docs say Credit-consuming calls are blocked and are not automatically converted to pay-as-you-go.
How this relates to the earlier “Qwen 4 is in training” announcement
At Alibaba’s Apsara Conference on September 22, 2026, the company said the next-generation Qwen 4 model was in training and outlined a longer roadmap for Qwen 4.5 and Qwen 5, “projected to scale up to 5 to 10 trillion parameters.” That roadmap should not be read as a spec sheet for the preview available now. Official Model Studio docs describe Qwen4-Max-Preview as the next-generation flagship multimodal model, with the context, output, and access limits above; they do not publish a parameter count for this preview, and they do not say the 5–10 trillion figure applies to it.
Qwen3.8 models (including Qwen3.8-Max and Qwen3.8-Flash) remain listed as generally available Token Plan models. If you need a stable Qwen endpoint after November 25, 2026, official docs still point to those generally available IDs—not to a preview that is scheduled to be retired.
Should you switch to Qwen 4 now?
Try Qwen4-Max-Preview if you already have (or were going to buy) a Token Plan seat, you can use it interactively in a supported coding or agent tool, and you want to test Alibaba’s next flagship while the preview discount is in effect. The 1M-token context, default xhigh thinking, multimodal inputs, and OpenAI/Anthropic API compatibility make it a straightforward trial for teams already in the Qwen or Token Plan ecosystem. Off-peak hours (22:00–08:00 UTC+8) are the cheapest official Credit rate during the window.
Wait, or stay on Qwen3.8, if you need a model that will still be there after November 25, you need pay-as-you-go billing, or your use case is a backend/batch integration that Token Plan Personal Edition policy does not allow. Because thinking tokens share the 393,216 output budget and thinking is on by default at xhigh, a casual “just change the model ID” test can also burn Credits faster than a flash-tier Qwen3.8 call unless you lower reasoning_effort for simple tasks.
Primary official links: the Qwen4-Max-Preview model docs, the Model Studio release notes, the Token Plan Personal Edition overview, Token Plan product updates, the Token Plan quick start, and the September 22, 2026 Apsara Conference press release.
Sources verified Nov 14, 2026 (Pacific Time): Alibaba Cloud Model Studio, “qwen4-max-preview (Latest Model),” last updated Nov 13, 2026; Alibaba Cloud Model Studio, “Model releases and updates,” last updated Nov 11, 2026; Alibaba Cloud Model Studio, “Token Plan (Personal Edition) Overview,” last updated Nov 13, 2026; Alibaba Cloud Model Studio, “Token Plan product updates,” last updated Nov 13, 2026; Alibaba Cloud Model Studio, “Token Plan Team Edition Quick start,” last updated Nov 11, 2026; Alibaba Cloud Model Studio, “Token Plan usage and quota,” last updated Nov 13, 2026; Alibaba Cloud, “Alibaba Unveils Roadmap on Full-Stack AI Strategy,” Sep 22, 2026.